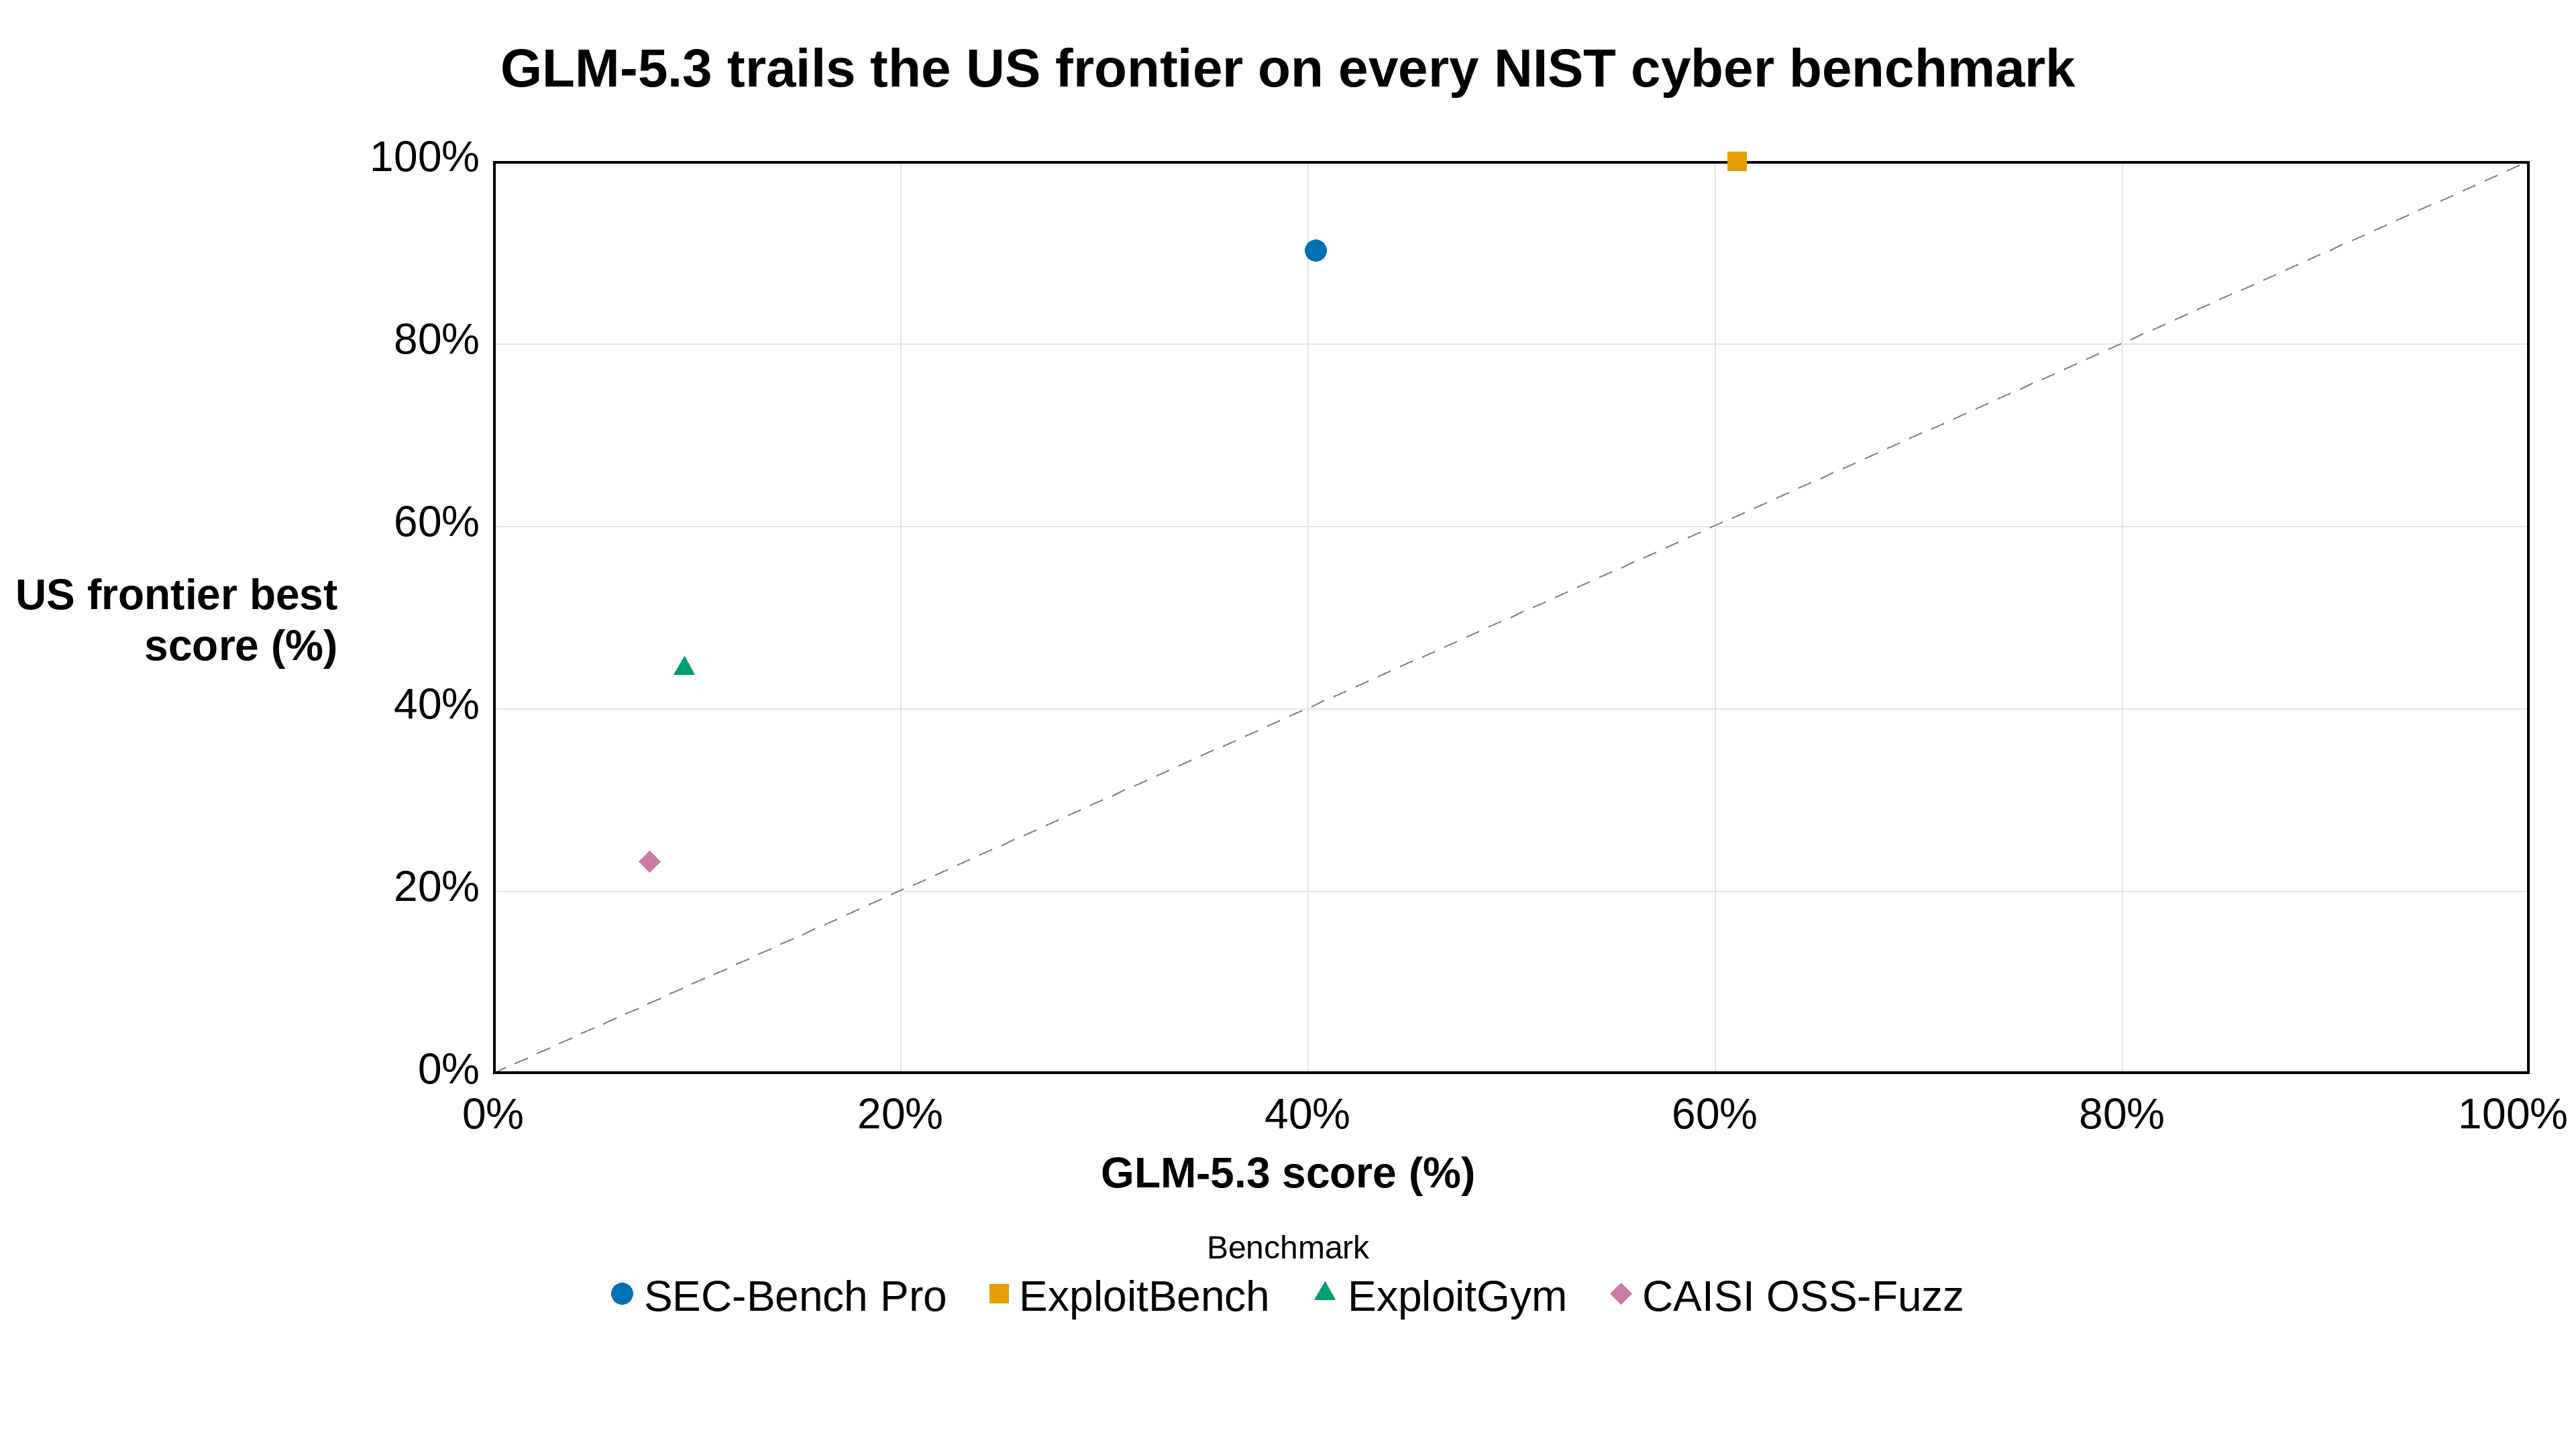
NIST’s CAISI assessment puts GLM-5.3 at 40.4% on SEC-Bench Pro, 61.1% on ExploitBench, 9.4% on ExploitGym and 7.7% on CAISI OSS-Fuzz, against US frontier bests of 90.2%, 100%, 44.4% and 23.2% — a gap of 16 to 50 percentage points on every benchmark. The same assessment still calls GLM-5.3 the most cyber-capable open-weight model released to date, about four months behind the US frontier overall, which is why the October 29 SI News finding — that it completed 3 of 13 Irregular multi-stage attack scenarios, the best open-weight result there — matters: the capability is downloadable, not gated behind an API.
Sources & Notes
- Original story: Chinese AI model carries out complex cyberattacks in tests (SI News, October 29, 2026)
- Data sources: National Institute of Standards and Technology, Center for AI Standards and Innovation (2026). CAISI’s Assessment of Z.ai’s GLM-5.3 Cyber Capabilities
- Other references: Baptista, E. (2026). Chinese AI model carries out complex cyberattacks in controlled tests, researchers say (Reuters, October 29, 2026)
- Notes: “US frontier best” is the best score per benchmark across US models CAISI evaluated, not a single model; US models were tested with cyber safeguards disabled where applicable. ExploitBench figures are mean scores on a 16-point scale (best of three attempts per task); the other three benchmarks are task success shares. All models ran in a ReAct harness at maximum reasoning. CAISI’s “about four months behind” is an aggregate estimate across its cyber benchmarks. Irregular’s CyScenarioBench scenario sets differ across models (GLM-5.3: 3 of 13; GPT-6 Astra: 9 of 10), so those counts are not directly comparable and are context only, not plotted.
Leave a comment