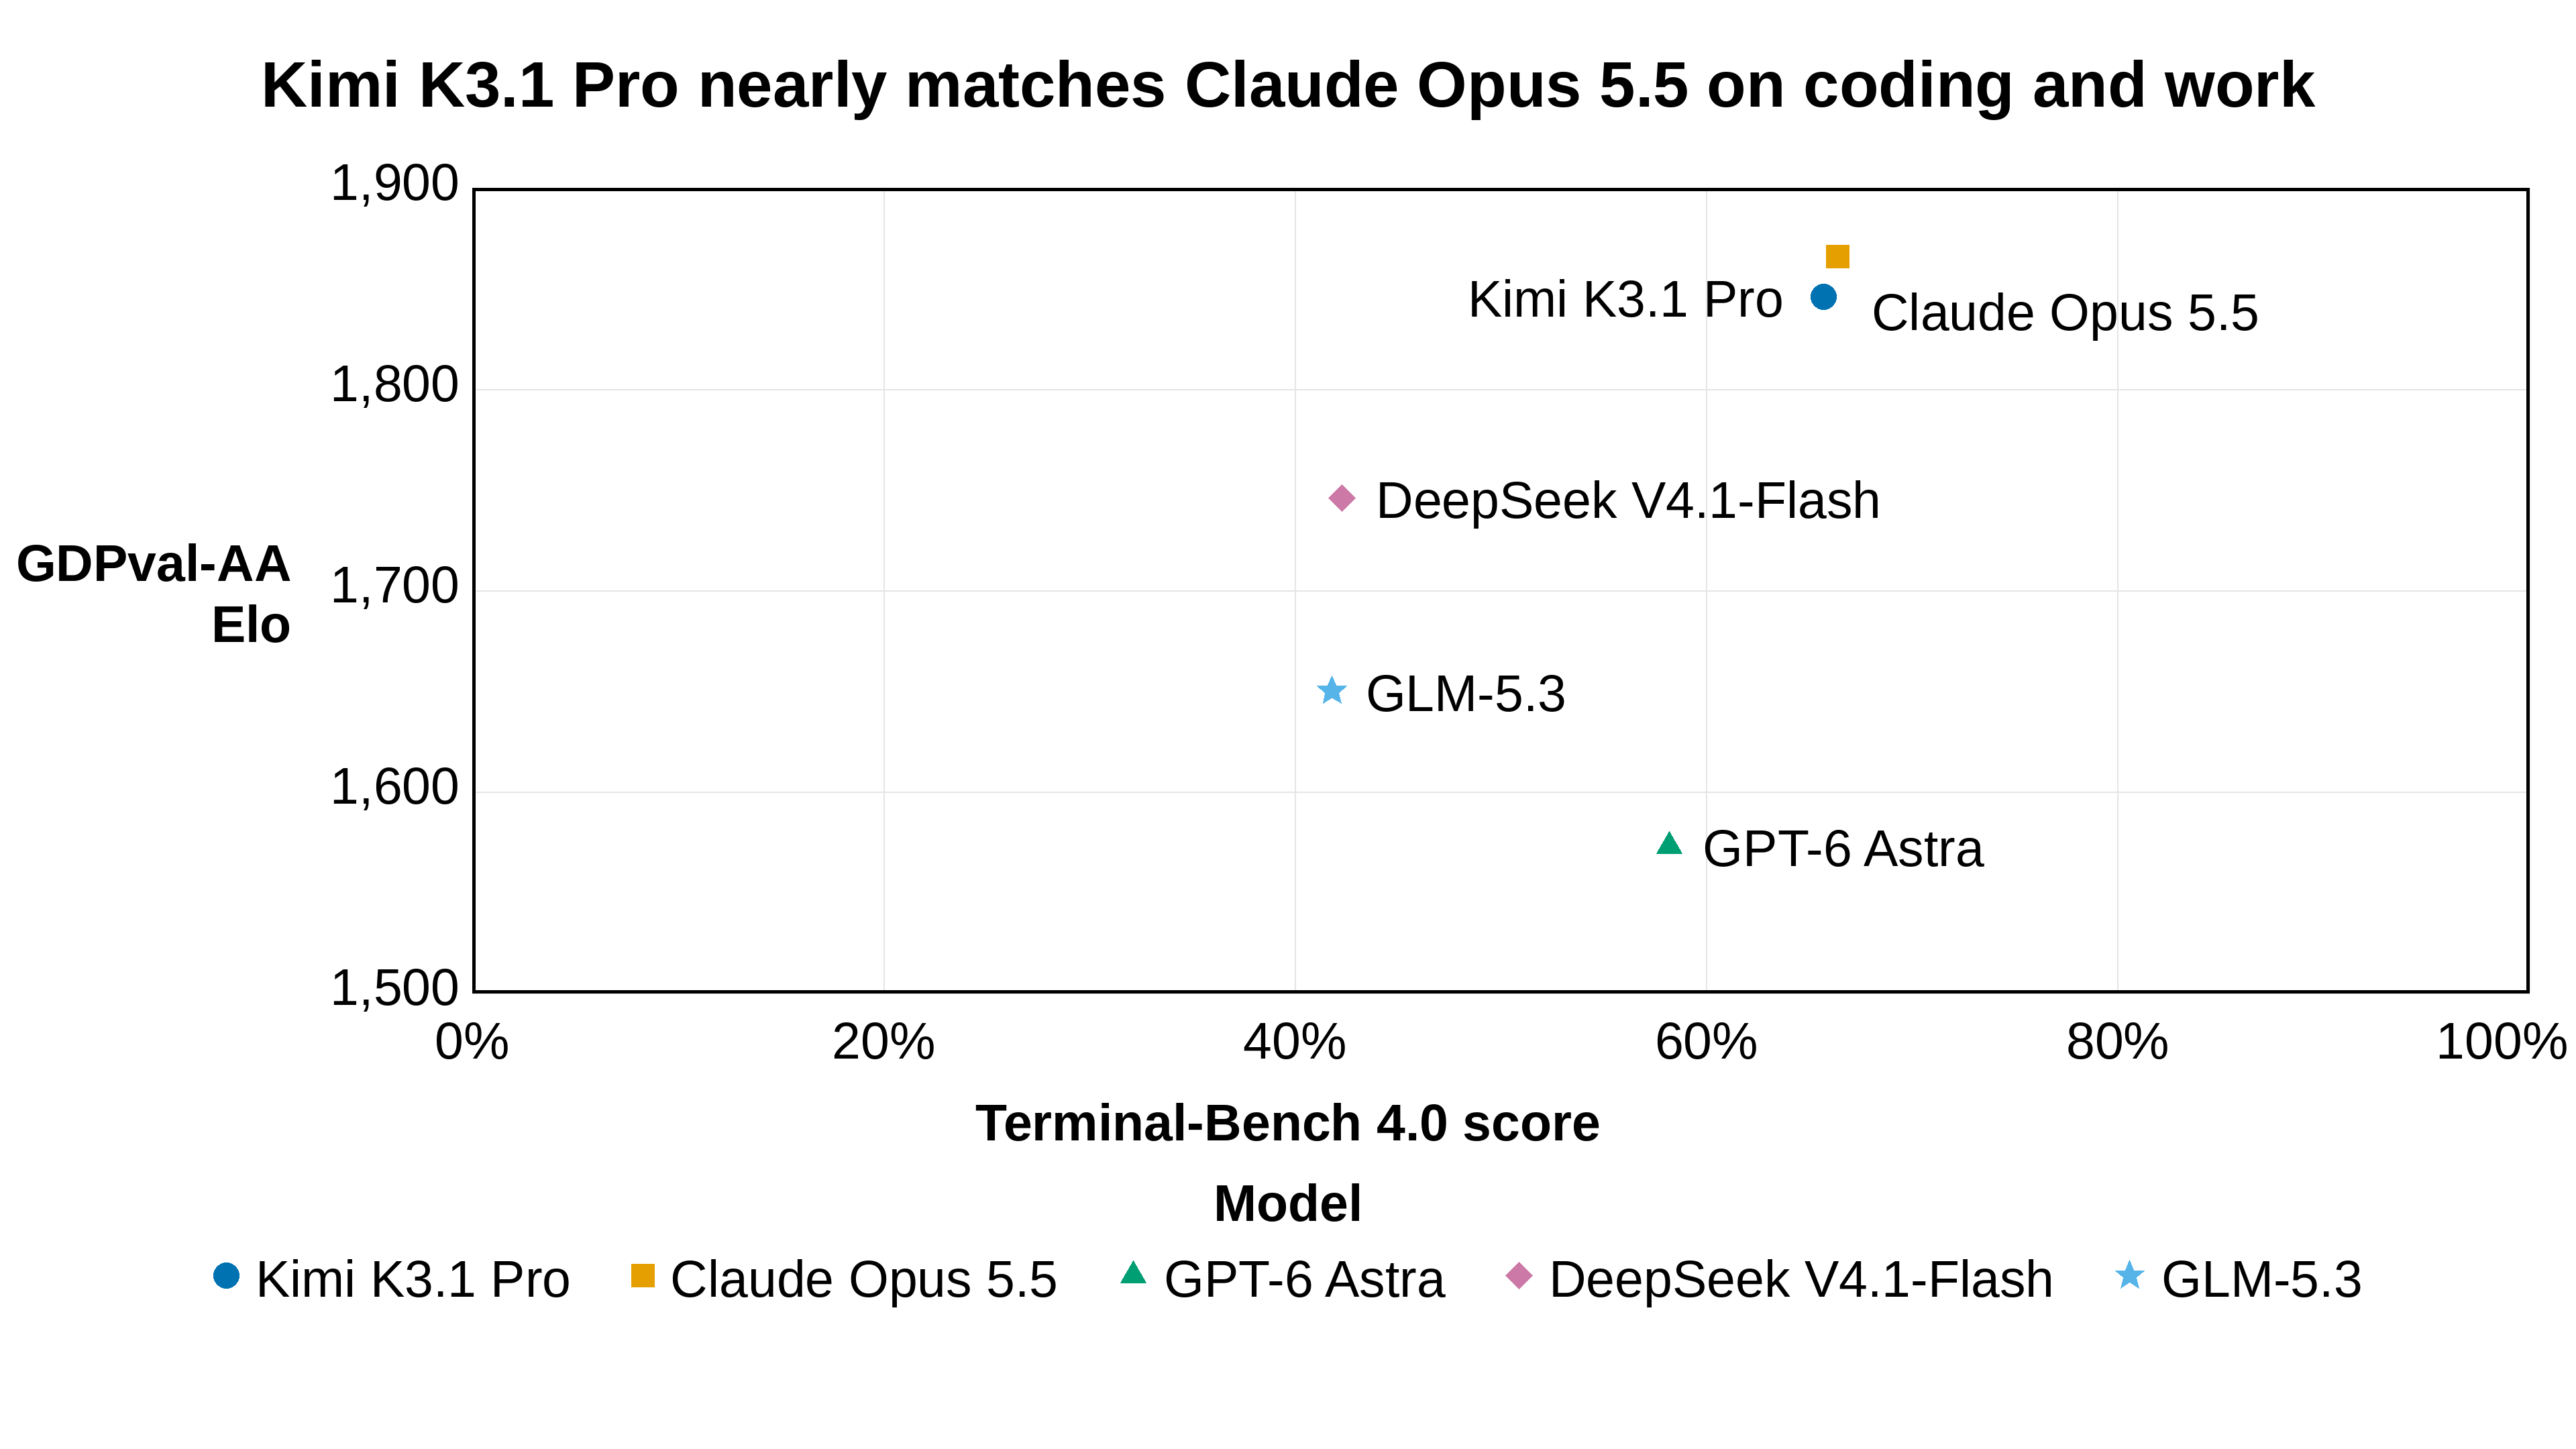
Moonshot’s comparison table puts Kimi K3.1 Pro at 65.7% on Terminal-Bench 4.0 and 1,846 Elo on GDPval-AA v2.1, within 0.7 points and 20 Elo of Claude Opus 5.5 (66.4%, 1,866) — the closest an open-weight model has come to the closed frontier on both measures at once. The two benchmarks diverge for DeepSeek V4.1-Flash, last on Terminal-Bench but third on GDPval, showing that coding and general work performance do not move together for every model. The data come from Moonshot’s K3.1 Pro comparison table, cross-checked against two independent reproductions, and connect to the October 24 SI News story on Kimi K3.1 Pro’s launch; a related SI Plots chart compares Kimi on Terminal-Bench versus BenchCAD.
Sources & Notes
- Original story: Kimi K3.1 Pro launches as a 3T-class open-weight model | OpenAI moves frontier training to offline environments
- Data sources: Moonshot AI (2026). Kimi K3.1 Pro comparison table
- Notes: Reasoning effort at maximum; rival scores from official leaderboards and technical reports. Artificial Analysis’ independent harness (67.2% Terminal-Bench for K3.1 Pro) was not mixed in, as it uses a different harness. The Y axis runs 1,500–1,900 Elo (Elo is an interval scale). K3.1 Pro is a post-trained Kimi K3 (2.8T total / 104B active parameters, 1M context); weights were promised by November 4.
Leave a comment