Entries for October 2026

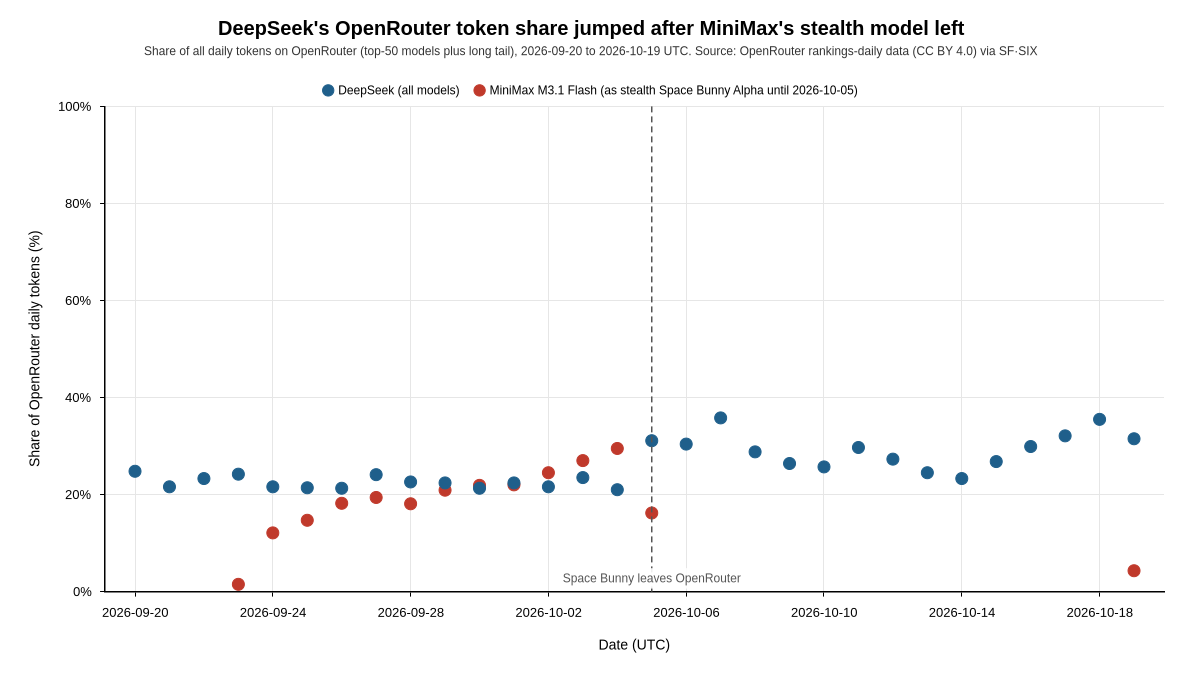
DeepSeek’s OpenRouter token share rose from 22% to 29% after MiniMax’s stealth Space Bunny left

Scatter chart of daily share of OpenRouter tokens, 2026-09-20 to 2026-10-19: MiniMax's stealth Space Bunny rises to 29.5% then leaves on 2026-10-05, after which DeepSeek's share rises from about 21% to 29-36%

OpenRouter’s daily token data show MiniMax’s anonymous Space Bunny Alpha climbing from 1.5% of all tokens on 2026-09-23 to 29.5% on 2026-10-04, 56.7 trillion tokens in total (matching OpenRouter’s own reveal figure), before it left the platform on 2026-10-05. DeepSeek’s combined share averaged 22.1% during Space Bunny’s run (2026-09-24 to 2026-10-04), jumped from 21.0% to 31.1% the day it left, and averaged 29.1% from 2026-10-06 to 2026-10-19; the timing fits users of the free stealth model moving to DeepSeek, though the aggregate data cannot show where individual users went. It matters for two stories in SI News’s MiniMax M3.1 Flash item and its report on the U.S. DeepSeek ban: the relaunched M3.1 Flash took 4.3% of tokens on its first (free) day, and DeepSeek, now barred from federal civilian agency systems, was still OpenRouter’s largest model developer at 31.5% of tokens on 2026-10-19.

Sources: OpenRouter rankings (daily tokens per model from the rankings-daily dataset, CC BY 4.0; Source: OpenRouter (openrouter.ai/rankings), as of 2026-10-20T08:29:15Z), retrieved via the SF·SIX usage snapshot (SF·SIX most-used models page) · OpenRouter, Space Bunny Alpha model page (released 2026-09-23, revealed as MiniMax M3.1 Flash) · MiniMax, M3.1 Flash launch post · DHS order on DeepSeek, Federal Register 2026-21447
Original stories: SI News: Anthropic 5% shares into public benefit fund | MiniMax model M3.1 Flash with 1M context | Hybrid Reasoning Agents · SI News: U.S. bans DeepSeek from federal civilian agency systems
Notes: Shares are each developer’s tokens divided by all OpenRouter tokens that day (top-50 models plus the aggregated long-tail row), UTC days. DeepSeek includes all of its listed models. Token counts come from each provider’s own tokenizer, so cross-developer shares are approximate, and the data cover OpenRouter traffic only, not global use. Space Bunny Alpha and the 2026-10-19 M3.1 Flash listing were free to use.
• 0 Comments

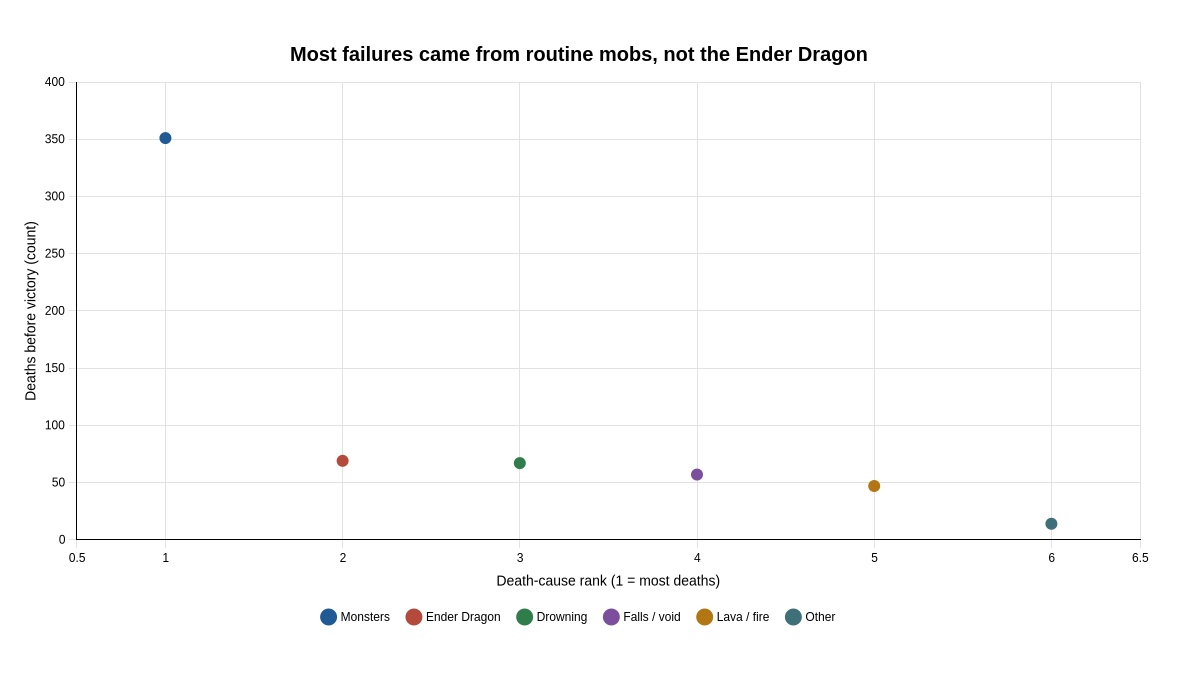
Routine monsters caused 58% of Gemini agents’ 605 Minecraft deaths

Most failures came from routine mobs, not the Ender Dragon

Of 605 deaths logged before victory, 351 (58.0%) came from ordinary monsters, versus 69 (11.4%) from the Ender Dragon; drowning (67), falls or the void (57), lava or fire (47), and other causes (14) made up the rest. The primary paper’s server-log breakdown shows that the dominant reliability burden in this 27-hour autonomous run was routine environmental hazards, not the final boss. This adds quantitative failure-mode detail to SI News’s report that four Gemini 4 Argon agents completed Minecraft without human help.

Original SI News story: Gemini 4 agents complete Minecraft autonomously

Data sources


Categories: AI

• 0 Comments

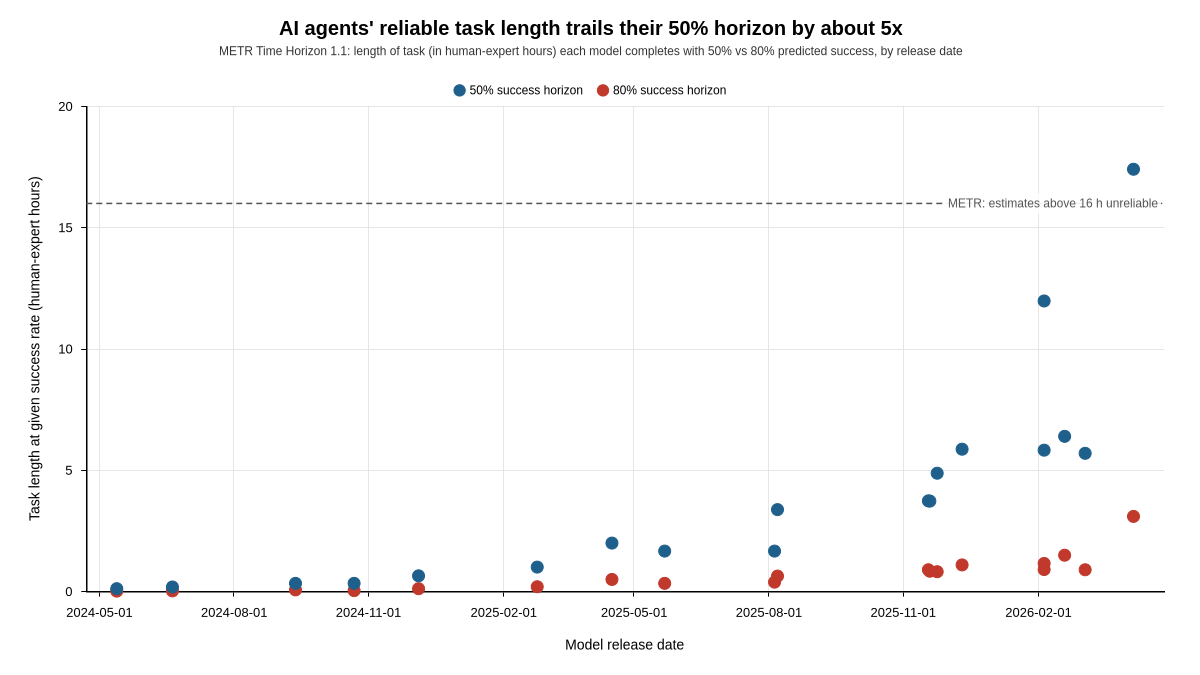
AI agents’ 80%-reliable task length runs about 5x shorter than their 50% horizon

Scatter plot of METR 50% and 80% success time horizons in human-expert hours by model release date, 2024-05 to 2026-04

Across 19 models released between 2024-05-13 and 2026-04-07 in METR’s Time Horizon 1.1 data, the task length a model completes with 80% predicted success is a median 5.3x shorter (range 4.0x to 10.3x) than the length it completes with 50% success. The most recent point, an early Claude Mythos Preview, reaches 17.4 human-expert hours at 50% but only 3.1 hours at 80%, and METR cautions that estimates above 16 hours are unreliable. The gap matters because attackers can tolerate frequent failure: in the AI-agent hacking campaign covered in today’s SI News brief, Reuters reports that the agents attempted more than 1,200 sites and compromised more than 100, while businesses deploying agents generally need the reliable end of the curve.

Sources: METR, Task-Completion Time Horizons of Frontier AI Models (Time Horizon 1.1 data file; p50 and p80 horizon estimates and release dates) · Reuters (republished by RTÉ) · NorForge, Inside Cairn
Original story: SI News: Agents that hack, Anthropic’s public-benefit fund, Disney’s Character.AI hire
Note: METR’s horizon measures how long the tasks take human experts, not how long an agent runs. Points are point estimates; METR’s confidence intervals are wide (Claude Mythos Preview at 50%: 8.5 to 55 hours).

• 0 Comments

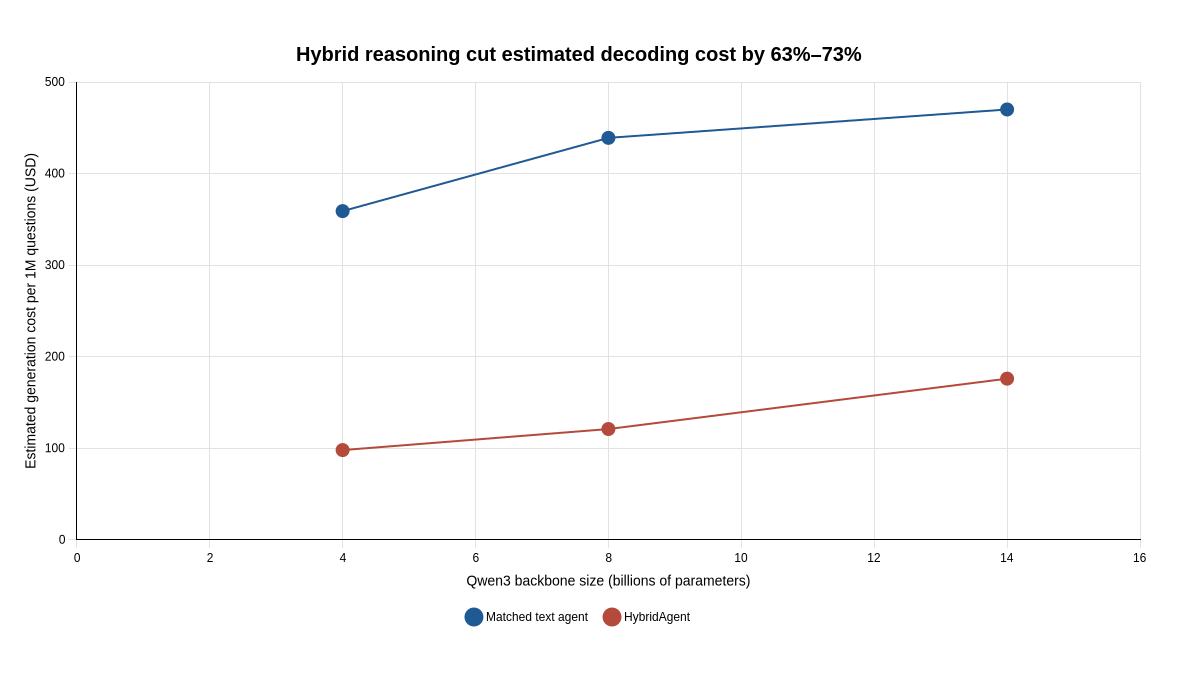
Hybrid reasoning cut estimated decoding cost by 63%–73%

Hybrid reasoning cut estimated decoding cost by 63%–73%

In the authors’ matched evaluation, estimated generation cost per million questions fell from $359 to $98 at 4B parameters, $439 to $121 at 8B, and $470 to $176 at 14B. That is a 62.6%–72.7% reduction, although the estimate assumes $2.50 per H100-hour and 10% utilization and excludes prompt prefill, context-dependent attention, and external tool execution. The result adds cost detail to SI News’s report on Hybrid Reasoning Agents, showing that their shorter decoded trajectories could materially reduce inference expense even after latent steps are charged as full backbone passes.

Original SI News story: 1. Anthropic 5% shares into public benefit fund. 2. MiniMax model M3.1 Flash with 1M context. 3. Stanford + UIUC + Together AI on "Hybrid Reasoning Agents".

Data sources

Categories: AI

• 0 Comments